01 / Research question
Peptide representations need to accommodate non-canonical amino acids beyond the usual sequence alphabet.
02 / Innovation
Learn at atom and fragment scales with a heterogeneous graph, masked-fragment self-supervision and canonical-to-non-canonical pretraining.
03 / Mechanism
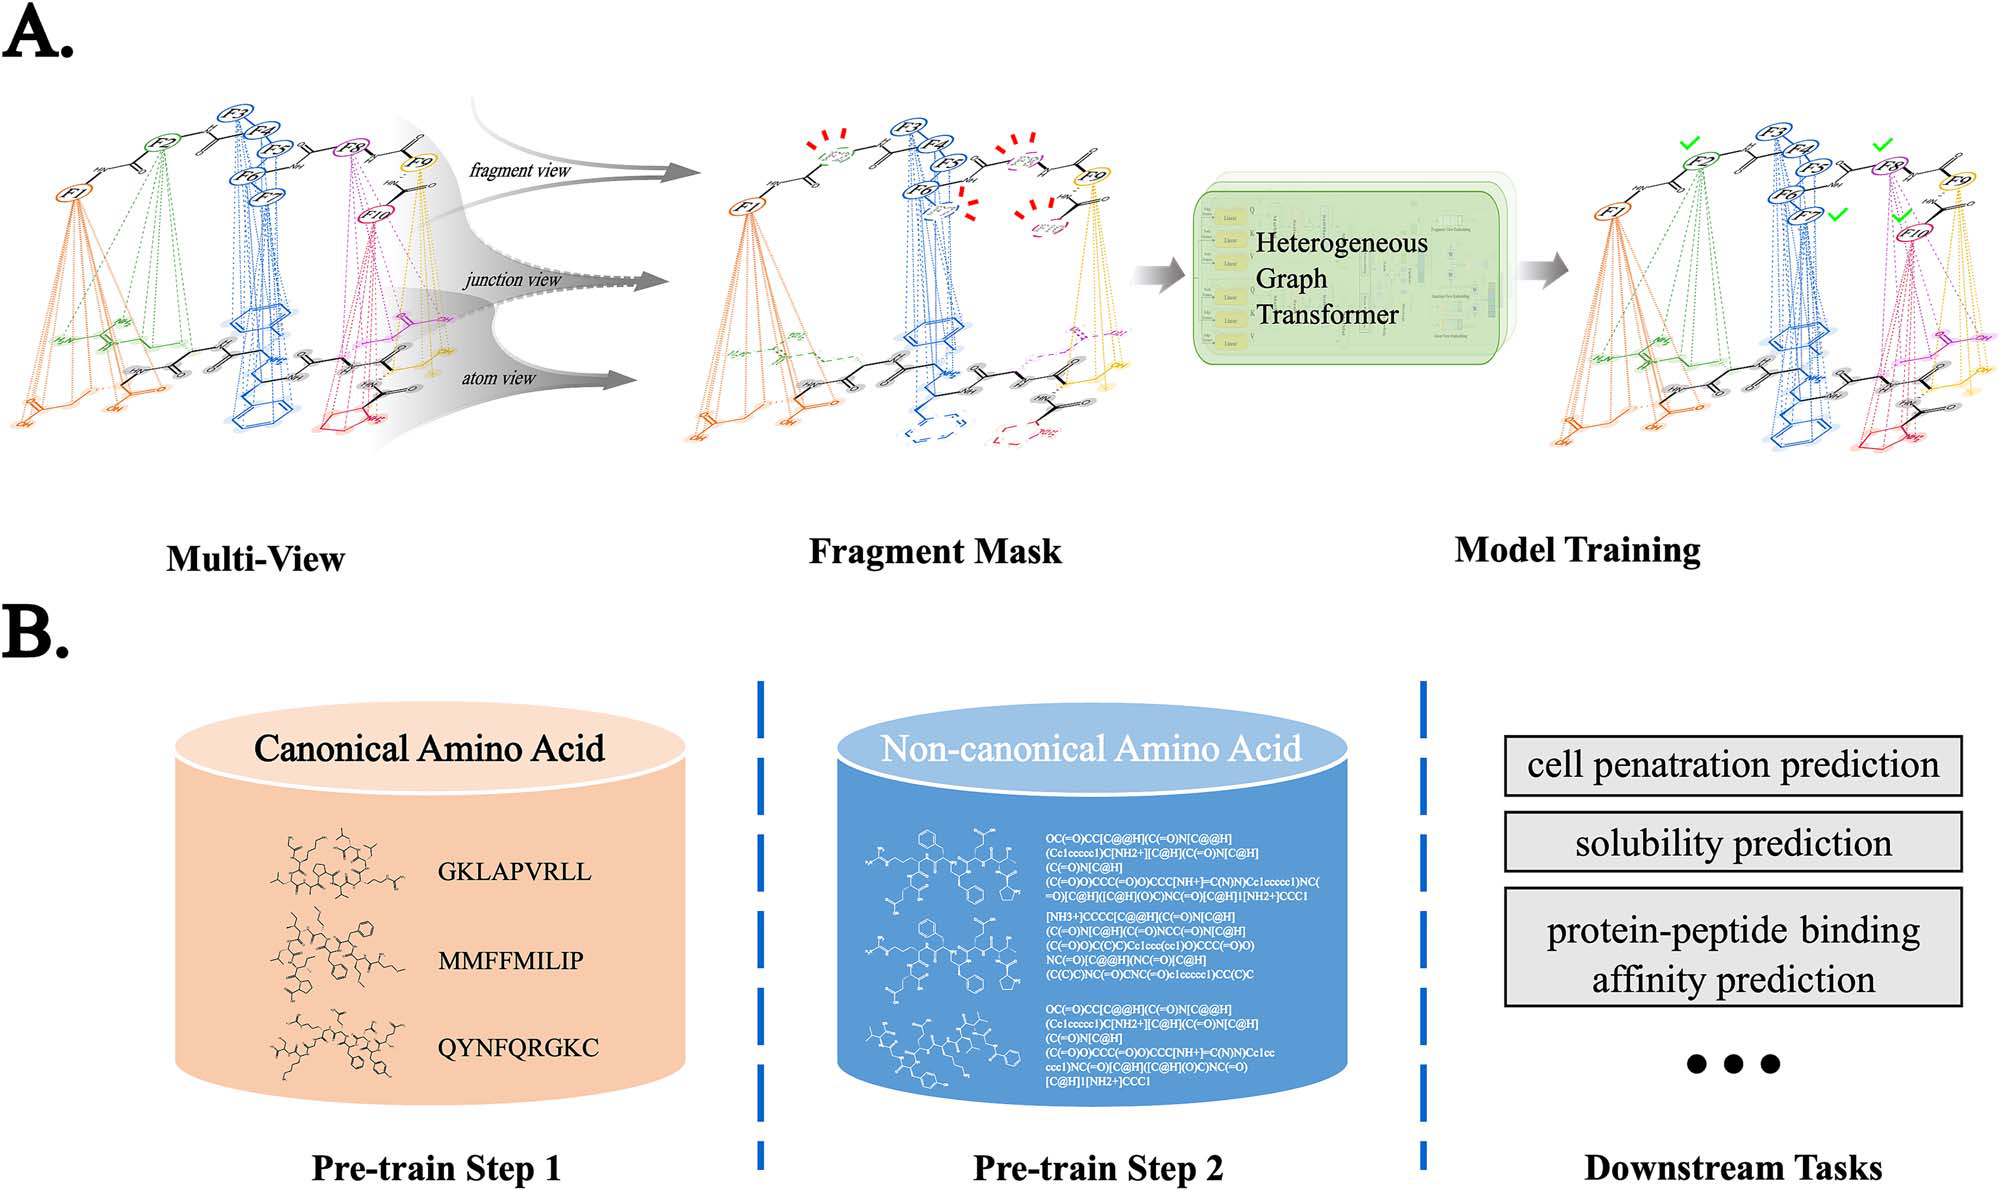
AdaFrag combines amino-acid fragmentation with BRICS side-chain fragments. Atom, fragment and junction relations exchange information in a heterogeneous graph. Masked pretraining first learns canonical chemistry, then adapts to noncanonical peptides.
04 / Experimental setup
The 2023 manuscript uses 7,924,509 first-stage samples and 8,977 noncanonical second-stage peptides. Downstream tasks include CPP (1,162 positives/1,162 negatives), short-sequence PROSO-II solubility and peptide affinity. ESM and small-molecule encoders are compared. Exact downstream split ratios are not stated in the inspected main text.
Author manuscript · 2023 · Tables 2, 3, 5 · Source ↗
05 / Results
Noncanonical affinity PCC reaches 0.873 after two-stage training. Canonical CPP AUC is 0.838 versus ESM 0.885. These are 2023 manuscript values, not the 2025 journal tables.
ORIGINAL FIGURE / PAPER SOURCE
How the method works.
AdaFrag adds BRICS side-chain fragments to amino-acid fragmentation, placing canonical and noncanonical chemistry in one atom/fragment heterogeneous graph. Masked learning builds representations, then two-stage pretraining adapts them to noncanonical peptides.
REPORTED COMPARISON / SAME-PAPER CONDITIONS
Comparisons, including the tradeoffs.
Author-reported results from the public 2023 manuscript; values belong to that version rather than the final-journal tables. Check original tables ↗
Swipe horizontally or focus and use arrow keys for all columns →
| Model | AUC ↑ |
|---|---|
| ESM | 0.885 |
| PepLand | 0.838 |
| ESM + PepLand | 0.885 |
PepLand alone trails ESM on this canonical CPP task; noncanonical tasks are a major focus. No cross-paper leaderboard is implied because splits and protocols are not aligned.
ABLATION / WHAT CHANGES THE RESULT?
Take the mechanism apart.
Swipe horizontally or focus and use arrow keys for all columns →
| Condition | Task / metric | Reported value |
|---|---|---|
| Amiibo | Noncanonical affinity SCC | 0.708 |
| AdaFrag | Noncanonical affinity SCC | 0.749 |
| Amiibo → AdaFrag | Solubility F1 | 0.696 → 0.693 |
| One stage → two stages | Noncanonical affinity PCC | 0.827 → 0.873 |
| One stage → two stages | Canonical affinity PCC | 0.496 → 0.450 |
Source: 2023 manuscript Tables 3 and 5. Side-chain fragmentation and two-stage training do not improve every metric.
A BOUNDED CASE / REPRESENTATIONS IN CONTEXT
Back to a peptide question.
1SMF
Public manuscript Figure 8: 6 samples, Spearman 0.829. A curated SKEMPI case excluded from training.
View public structure ↗5XCO
Public manuscript Figure 8: 10 samples, Spearman 0.718. A small retrospective case, not prospective candidate discovery.
View public structure ↗06 / Ablation & limitations
Tables 3–5 compare fragmentation, masking and training stages. Two stages increase noncanonical-affinity PCC from 0.827 to 0.873, but canonical-affinity PCC falls from 0.496 to 0.450. Representation quality remains task-dependent; small retrospective cases do not establish prospective candidate discovery.
Representation learning does not establish an experimentally confirmed therapeutic candidate. Generalization depends on the exact task, split and evaluation conditions.
07 / My contribution
First author.
08 / Paper & code
Cite this research
PepLand: a large-scale pre-trained peptide representation model for a comprehensive landscape of both canonical and non-canonical amino acids. Briefings in Bioinformatics · 26(4), bbaf367, 2025. https://academic.oup.com/bib/article/26/4/bbaf367/8220755